
Insights
AI Spend Visibility Case Study: From Bill to Owner
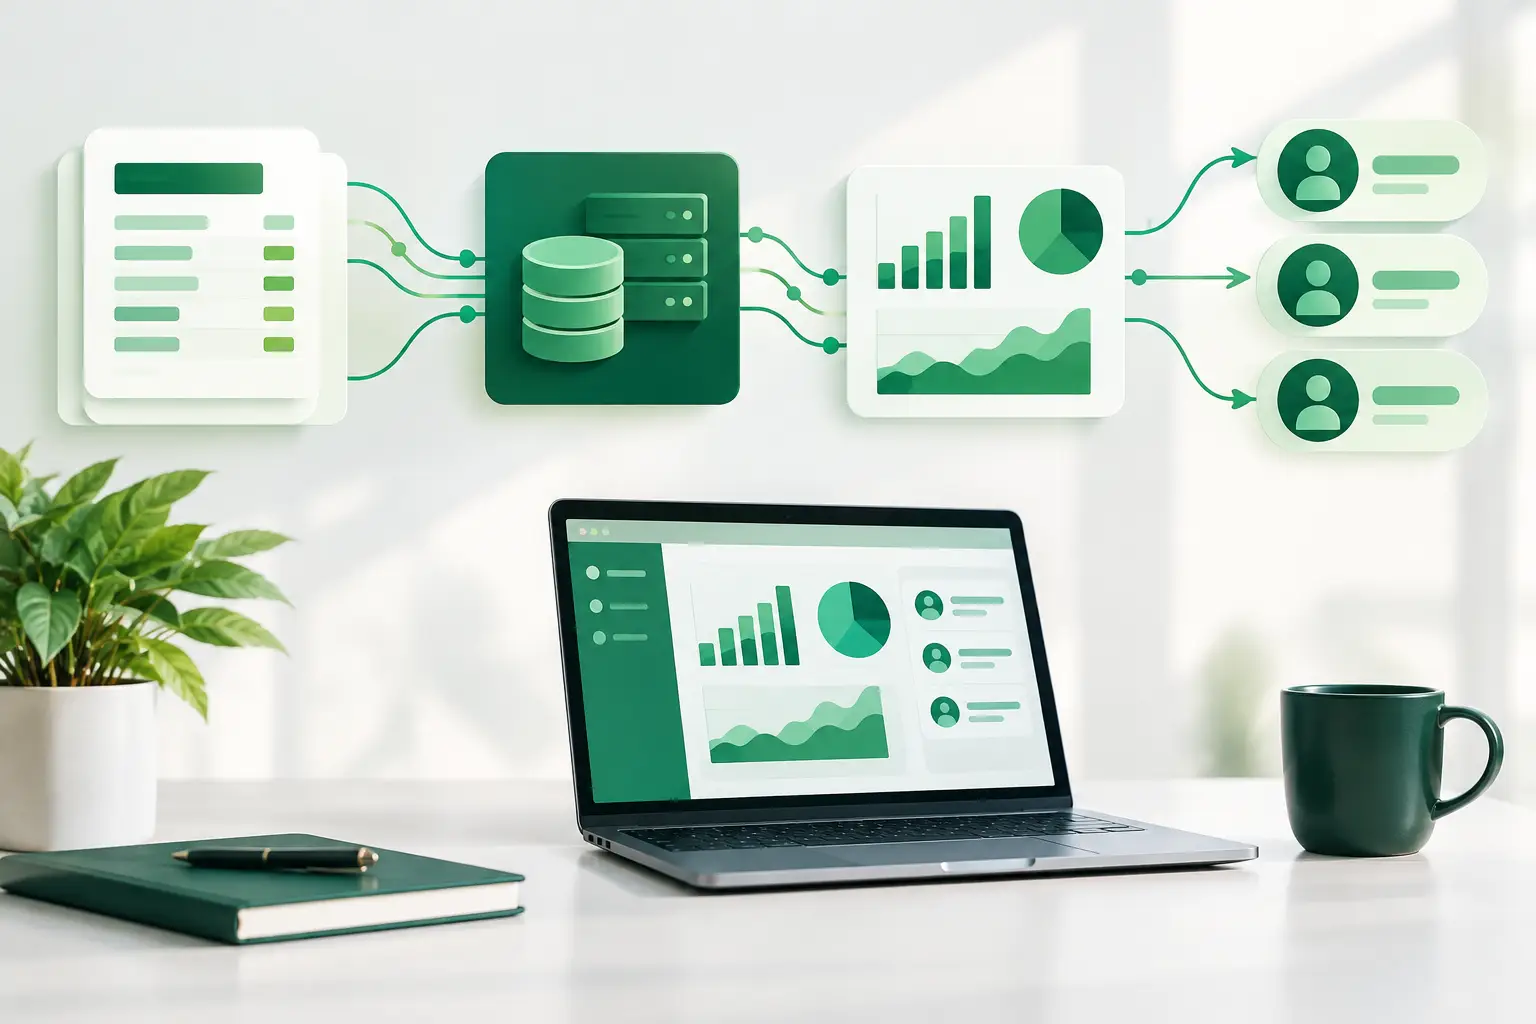
A $184,000 monthly AI bill arrived with three vendor invoices, several cloud charges, and no usable owner field. Finance could see the total. The platform team could see tokens, requests, and gateway logs. Neither group could answer the CFO's basic question: which business activity created the cost? This AI spend visibility case study shows how one composite enterprise operating model turned that gap into a repeatable allocation and accounting process.
The company in this example is a U.S.-based services business with about 4,000 employees. Over 12 months, teams had put generative AI into customer support, sales research, software development, document processing, and internal knowledge search. Adoption was encouraged, but costs were treated as a central technology expense. That arrangement worked while spending was small. It became a problem once monthly usage moved into six figures.
This is an illustrative composite, not a claim about a single customer. The details reflect the operating patterns finance and technology teams encounter when AI use reaches production scale.
AI spend visibility case study: the operating problem
The company had seven material sources of AI cost: direct model-provider accounts, cloud AI services, a gateway, embedded AI features in software tools, and GPU-related cloud infrastructure. Procurement had negotiated some of the contracts. Engineering owned others. Several business teams had expense cards for pilots that had quietly become recurring workloads.
The month-end process revealed the fault line. Accounts payable coded most invoices to a shared technology cost center because invoice lines did not identify the consuming team. FP&A forecasted AI expense using a flat monthly run rate. Engineering could estimate activity from logs, but its data was organized around API keys and environments, not legal entities, cost centers, or budget owners.
That created three practical failures. First, business leaders could not see the full cost of the AI capabilities they sponsored. Second, finance could not distinguish a temporary spike from a durable increase in unit cost. Third, no one had a credible basis to decide whether to limit a workload, redesign it, or keep funding it because its business return justified the cost.
The objective was not to reduce every dollar of AI spend. It was to establish ownership. Cost control without attribution often leads to blunt restrictions that slow useful work while leaving waste hidden in shared accounts.
Start with a cost model, not a dashboard
The joint finance and platform team first agreed on what belonged in the AI cost pool. This sounds elementary, but it is where many programs fail. A dashboard that captures only model API invoices can understate the cost of a production agent materially.
For this company, the monthly AI cost pool included model inference and embedding usage, managed AI platform fees, gateway charges, GPU compute dedicated to model workloads, and the portion of shared cloud services directly required to run agents. It excluded general engineering labor and broad corporate software because allocating those items would add complexity without producing a decision-ready number.
Then the team established a simple hierarchy for attribution: legal entity, business unit, cost center, project, application, agent, environment, and vendor account. Not every source could populate every field on day one. The rule was to retain the most specific verified identifier available and flag records that fell short of the required standard.
This distinction matters. An API key tells the platform team how traffic was authenticated. A cost center tells finance who owns the expense. A usable system needs both.
Meter direct use wherever possible
For direct API and cloud AI usage, the company tagged each request or workload with a project and cost center. Customer support's answer-generation agent, for example, carried a support operations cost center and a service project code. The sales research workflow carried a revenue operations code. Development environments were kept separate from production so experimentation did not disappear into the same spend line as customer-facing services.
The metering record captured the vendor, model family, token or request quantity, unit price where available, date, environment, and ownership tags. The platform team did not need to expose prompt contents to finance. Finance needed financial dimensions and auditable consumption evidence, not sensitive application data.
Allocate shared costs with a stated basis
Some costs could not be directly metered. The gateway's fixed platform fee, for example, supported multiple teams. Rather than spreading it evenly, the company allocated it using each team's share of metered AI request volume. GPU clusters used by several document-processing workloads were allocated by measured GPU-hours.
The allocation basis should follow the underlying cost driver where practical. Request share may be reasonable for a gateway fee. It is a poor choice for a workload in which one team uses far longer context windows than another. For model costs, actual tokens, requests, or provider-reported usage are usually better than headcount or an equal split.
The company documented each rule, its source data, its owner, and the review cadence. That documentation is not bureaucracy. It gives controllers a way to explain why one cost center received an expense and gives business leaders a way to challenge a rule with evidence.
Turn usage into accounting entries
Once the company could calculate consumption by owner, it needed to make the result usable in the ledger. A monthly showback report alone would improve conversations, but it would not correct the accounting problem.
At month-end, finance booked vendor invoices and accrued usage not yet invoiced to a central AI clearing account. The allocation engine then produced cost-center-level entries. If support operations consumed $31,400 of direct model usage and received $2,600 of shared gateway cost, the internal entry was:
```text Debit: AI Expense - Support Operations $34,000 Credit: AI Clearing - Central Technology $34,000 ```
Sales operations, product, and engineering received equivalent entries for their measured or allocated share. The central clearing account reconciled to invoices, cloud billing exports, and approved accruals. Finance could now see both the total external obligation and the internal owner distribution.
Whether to use chargeback or showback depended on the company's management model. In the first two quarters, leadership used showback: costs appeared in departmental reporting but did not reduce operating budgets. That gave teams time to validate tagging and adjust architecture without turning the first report into a budget dispute. Once data completeness exceeded the agreed threshold and allocation variances were understood, the company moved selected production workloads to chargeback.
That sequence is often more effective than imposing chargeback immediately. A chargeback model with weak data creates distrust. A showback period gives the organization time to fix ownership gaps before money moves.
What changed after three reporting cycles
The most useful result was not a lower total bill in month one. It was a different operating conversation. The support organization learned that its agent cost was $0.42 per resolved case, including its allocated gateway share. That metric could be evaluated against handling-time savings and customer experience outcomes. The sales research workflow, by contrast, showed high spending during pilot activity but low recurring usage, so its budget forecast was revised downward rather than assumed to grow at the same rate.
Engineering also identified a document-processing workflow that accounted for a disproportionate share of token spend. The cause was not unusually high demand. The workflow was repeatedly sending oversized source material to the model. The application team changed its retrieval and document-chunking approach, reducing consumption without limiting the service.
For finance, the forecasting benefit was equally important. Instead of using one AI run rate, FP&A built forecasts from known workload drivers: cases handled, documents processed, active users, expected model mix, and committed platform fees. The forecast still included uncertainty, especially for new agents, but assumptions were visible and tied to operating plans.
The controls that kept the model credible
Visibility decays if ownership standards are optional. The company added a small set of operational controls: new production AI projects required a cost center and named business owner; shared accounts had an accountable technical owner; unmatched usage appeared in an exception report; and allocation rules were reviewed quarterly or when a material workload changed.
It also separated cost anomalies from business anomalies. A 40% increase in spend is not automatically a problem if support volume rose 45% and cost per case declined. Conversely, flat spend can conceal an issue if usage fell while unit cost increased. The relevant question is always whether the cost movement matches a known business or technical driver.
Tools such as Meridian are designed to make this operational by connecting AI usage to finance-ready dimensions, allocations, and journal entries. But the technology cannot choose ownership on the organization's behalf. Finance, platform engineering, and business leaders still need to agree on the cost model and act on the evidence it produces.
The practical starting point is smaller than many leaders expect: identify the AI cost pool, name the owners of the largest workloads, and reconcile one month of usage to one month of invoices. Once the first dollars have an accountable home, better budgets, unit economics, and control decisions become possible.
About Brian Diamond
Brian Diamond is a fractional Chief AI Officer who works with mid-market and enterprise organizations on AI strategy, governance, and operations. In 2001 he founded LanStatus, a managed services provider based in Trumbull, Connecticut, with named partnerships across Microsoft, HPE, Citrix, and VMware. He brings 25 years of infrastructure operations to AI leadership and publishes the CAIO Brief.
Also publishes at: day9.coffee · ChiliStation · PlotLuck · Beacon
Subscribe to the CAIO Brief for practical AI leadership every week.
Request an Onaro demo